
Hire an LLM engineer who's model-agnostic, by design.
Model-agnostic LLM engineering — RAG, fine-tuning, evals — added to your team on your terms.
Most LLM work isn't model research — it's retrieval pipelines, context engineering, cost/latency budgets, and evaluation discipline that holds up in production. Our LLM engineers are model-agnostic by design: we benchmark against your actual tasks rather than defaulting to one vendor, and we build the eval harness before we ship, not after something breaks.
- Seniority
- 5+ years, 2+ years focused on production LLM applications
- Background
- RAG pipelines, retrieval tuning, model evaluation, and cost/latency optimization across multiple model providers
What they'll actually do.
Not a job description — the work this person owns from their first sprint, inside your codebase and your process.
Work this bench has shipped.
Generative Catalog Intelligence for a Marketplace
A generative enrichment pipeline turning inconsistent seller listings into structured, search-optimized product data — descriptions, attributes, and categorization at catalog scale.
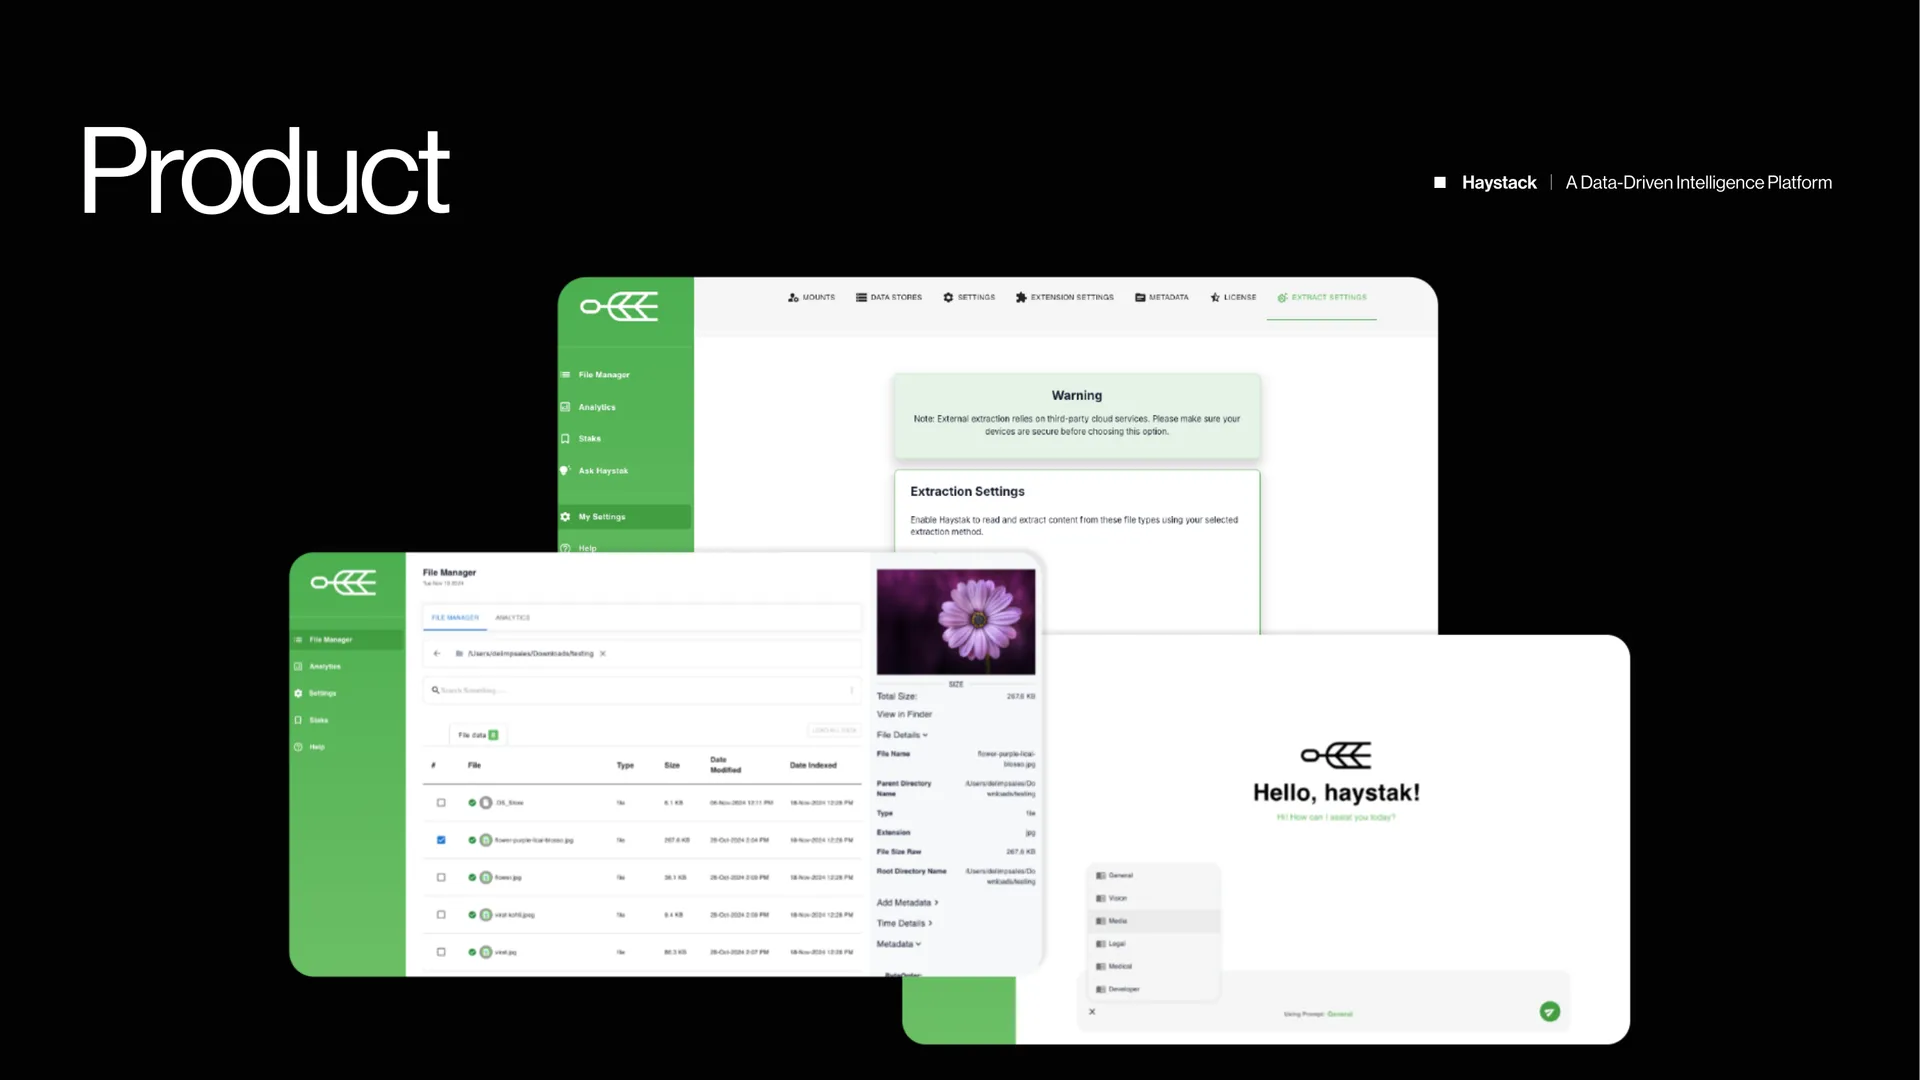
Haystack — AI Data Intelligence Platform
A data-driven intelligence platform: one AI search layer across documents, data lakes, and repositories, with real-time indexing, AI-driven correlation, and workflow automation — built to hold up under heavy data loads.
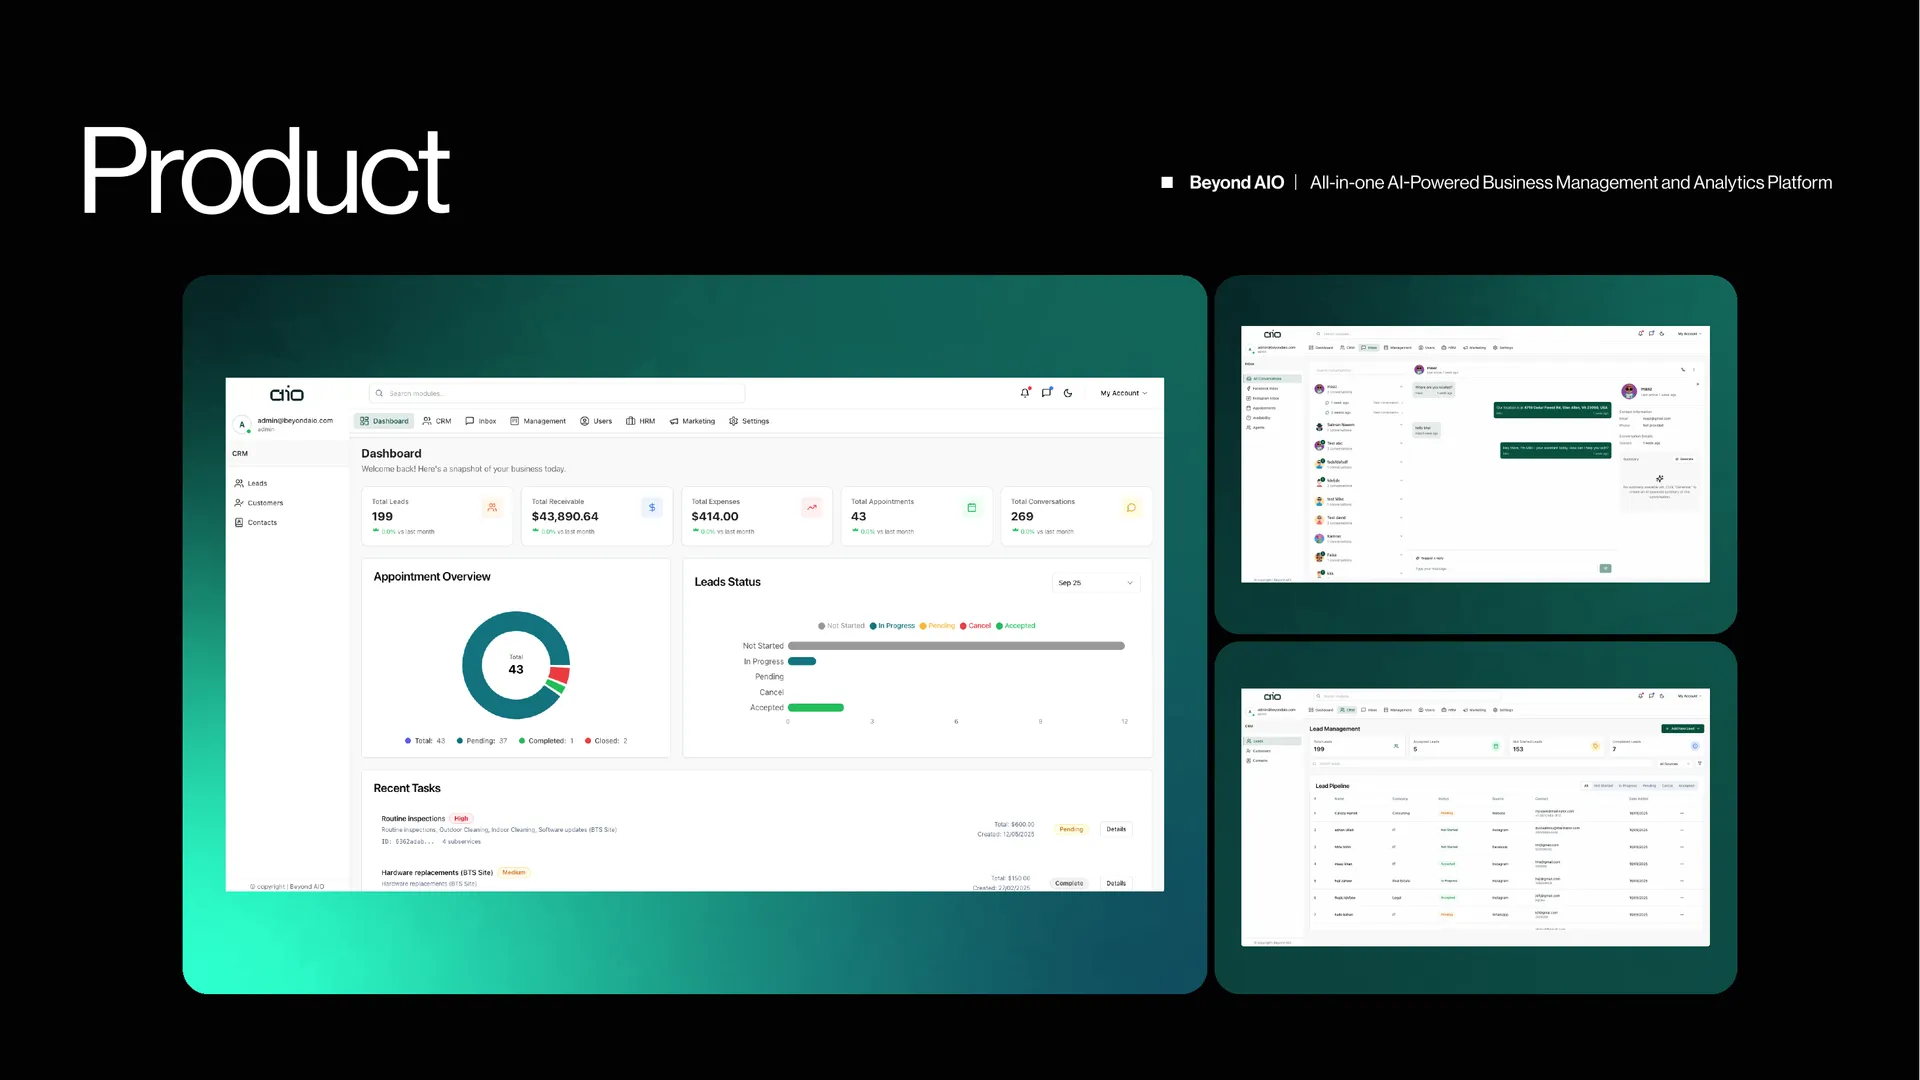
Beyond AIO — AI Business Management & Analytics Platform
An all-in-one AI-powered business platform: predictive analytics, competitor analysis, CRM, HRM, financial management, task management, and cross-channel marketing with real-time campaign optimization.
Disclosure — founder-owned venture
Tell us the role, the stack, and when you need them started.
Every figure has a name behind it.
No rounded-up vanity metrics — each number below is tied to a specific, named engagement this bench shipped.
From intro call to embedded.
Matched by senior engineers who've shipped production LLM systems themselves — not a recruiter matching keywords.
Intro call
Confirm the role, stack, and team fit in one call.
Match
We propose 1–2 engineers from the bench who fit the work, not a generic pool.
Trial week
A real first week of work before any longer commitment.
Embed
Full participation in your standups, sprints, and tooling.
If the fit isn't right, we replace them inside two weeks — no argument, no fee for the swap. You'd rather we caught it early, and so would we.
Asked on every first call.
An LLM engineer builds on whichever model benchmarks best against your actual tasks and your cost and latency constraints, rather than on a house default. The application layer is designed for portability, so changing provider later is a configuration decision rather than a rewrite, and you are not locked to one vendor's pricing.
Yes, and that is the default. A staff-augmentation LLM engineer works inside your codebase, your process and your standups, not in a separate vendor environment.
An LLM engineer typically starts within one to two weeks of the intro call. We match from an existing bench rather than opening a cold hiring pipeline, so the limiting factor is usually your onboarding and access paperwork rather than our recruiting.
Every LLM engineer placement carries a two-week replacement guarantee, with no argument and no fee for the swap. We would rather replace someone in week two than have you carry a bad fit for a quarter.
No. An LLM engineer is engaged day-rate or monthly, month-to-month after a four-week minimum. No tiers, no bundled products, no notice period designed to trap you.
You do, from the first commit. An LLM engineer works in your repositories under your version control, and all work product assigns to you — retrieval and application code, prompts, evaluation harnesses and golden datasets, and documentation. The IP assignment is signed before anyone is given repository access, not negotiated at handover.
One call. Then a name, not a pipeline.
- 30 minutes with a senior engineer, not a recruiter
- Free and no-obligation — bring the role and the stack
- You leave knowing who we'd match and how fast they can start
- We reply within one business day
Anthropic-certified engineering capacity for Claude-native products and agents.
Agent and workflow-automation engineering, embedded in your team.
Full-stack web and mobile engineering, AI-accelerated, senior-owned.
Fractional technical leadership for teams that need direction, not headcount.
Fractional AI leadership — roadmap, governance, and vendor decisions.
Retrieval pipeline engineering — the discipline behind every trustworthy RAG system.
Deployment, monitoring, and cost control for production AI systems.
Pipelines, warehousing, and AI-ready data infrastructure.
Systematic prompt and context design, tested against real outcomes.
Product management for AI features and roadmaps, grounded in what's actually feasible.
Let's put AI to work in your business.
A 30-minute call. You bring the workflow or the roadmap — we'll tell you what's feasible, what it costs, and what we'd build first.