
Hire an MLOps engineer who keeps it running after launch.
The infrastructure discipline that keeps AI systems running after launch, not just at demo.
Shipping a model once is easy; keeping it running, monitored, and cost-controlled in production is the actual job. Our MLOps engineers build the CI/CD, observability, and cost-tracking infrastructure that AI systems need to survive contact with real traffic.
- Seniority
- 5+ years infrastructure/platform engineering, 2+ years specifically on ML/AI deployment
- Background
- CI/CD for models and services, observability, cost/latency monitoring, Kubernetes
What they'll actually do.
Not a job description — the work this person owns from their first sprint, inside your codebase and your process.
Work this bench has shipped.
Concordia Colleges — 150-Branch SIS Platform
A complete Student Information System for a network of 150+ college branches: revenue and royalty management, fees, LMS, student and teacher operations, payroll, and accounts — unified on one platform.
Cove — Home Security Platform Consolidation
Operator portal, headless CMS, and marketing platform for a US home-security device ecosystem — three disconnected systems consolidated into one operator experience.
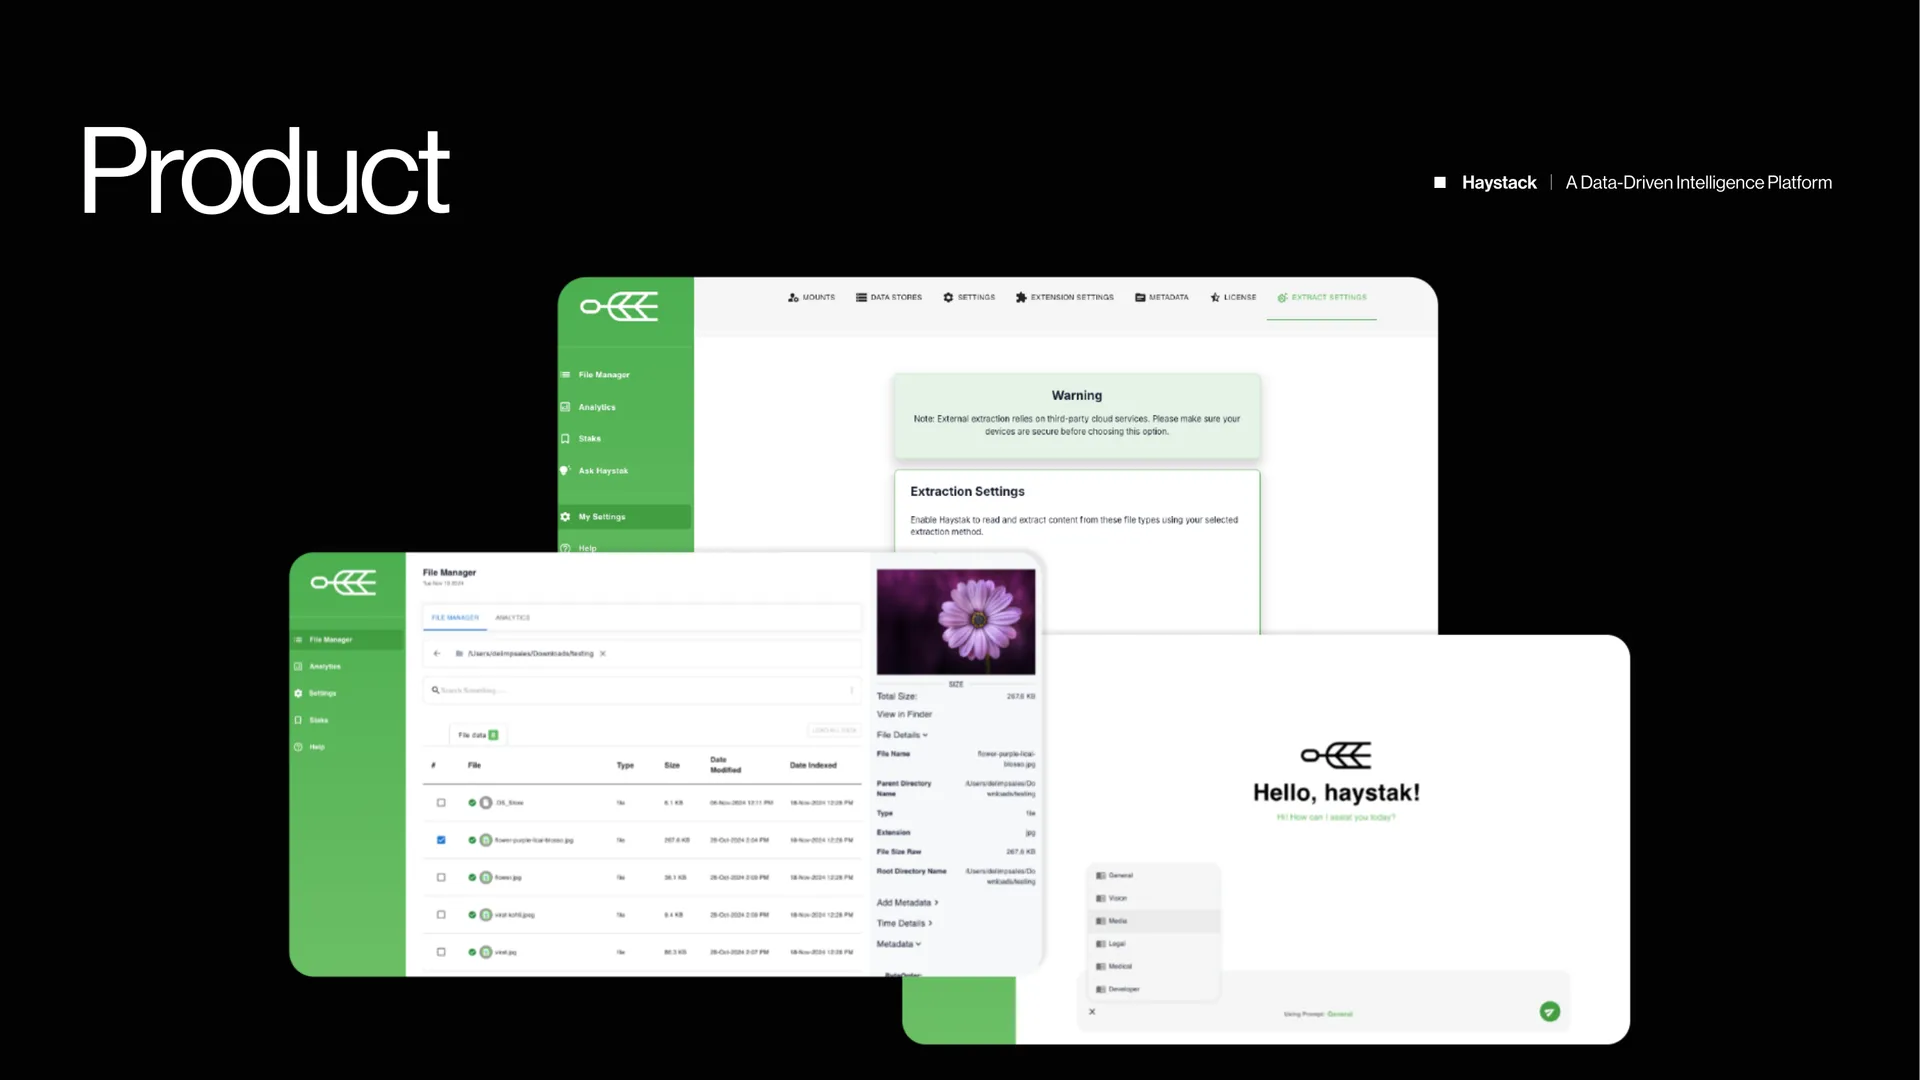
Haystack — AI Data Intelligence Platform
A data-driven intelligence platform: one AI search layer across documents, data lakes, and repositories, with real-time indexing, AI-driven correlation, and workflow automation — built to hold up under heavy data loads.
Tell us the role, the stack, and when you need them started.
Every figure has a name behind it.
No rounded-up vanity metrics — each number below is tied to a specific, named engagement this bench shipped.
From intro call to embedded.
Matched by engineers who've operated what they deployed — not just handed it off and moved on.
Intro call
Confirm the role, stack, and team fit in one call.
Match
We propose 1–2 engineers from the bench who fit the work, not a generic pool.
Trial week
A real first week of work before any longer commitment.
Embed
Full participation in your standups, sprints, and tooling.
If the fit isn't right, we replace them inside two weeks — no argument, no fee for the swap. You'd rather we caught it early, and so would we.
Beyond Technologies ensured a streamlined workflow with consistent project updates throughout — the platform now runs our entire network.
Asked on every first call.
Yes. An MLOps engineer works in AWS, Azure or GCP, and in hybrid setups where compliance requires part of the workload to stay put. We build on the platform you already run rather than migrating you to the one we would have picked.
Yes, and that is the default. A staff-augmentation MLOps engineer works inside your codebase, your pipelines and your standups, not in a separate vendor environment.
An MLOps engineer typically starts within one to two weeks of the intro call. We match from an existing bench rather than opening a cold hiring pipeline, so the limiting factor is usually your onboarding and access paperwork rather than our recruiting.
Every MLOps engineer placement carries a two-week replacement guarantee, with no argument and no fee for the swap. We would rather replace someone in week two than have you carry a bad fit for a quarter.
No. An MLOps engineer is engaged day-rate or monthly, month-to-month after a four-week minimum. No tiers, no bundled products, no notice period designed to trap you.
You do, from the first commit. An MLOps engineer works in your repositories and your cloud accounts, and all work product assigns to you — deployment pipelines, infrastructure-as-code, dashboards and alerting rules, and the runbooks that explain them. Nothing runs on infrastructure we hold, so there is no handover to negotiate later.
One call. Then a name, not a pipeline.
- 30 minutes with a senior engineer, not a recruiter
- Free and no-obligation — bring the role and the stack
- You leave knowing who we'd match and how fast they can start
- We reply within one business day
Anthropic-certified engineering capacity for Claude-native products and agents.
Senior LLM application engineering, without the vendor lock-in.
Agent and workflow-automation engineering, embedded in your team.
Full-stack web and mobile engineering, AI-accelerated, senior-owned.
Fractional technical leadership for teams that need direction, not headcount.
Fractional AI leadership — roadmap, governance, and vendor decisions.
Retrieval pipeline engineering — the discipline behind every trustworthy RAG system.
Pipelines, warehousing, and AI-ready data infrastructure.
Systematic prompt and context design, tested against real outcomes.
Product management for AI features and roadmaps, grounded in what's actually feasible.
Let's put AI to work in your business.
A 30-minute call. You bring the workflow or the roadmap — we'll tell you what's feasible, what it costs, and what we'd build first.